
What it finds, and what it saves
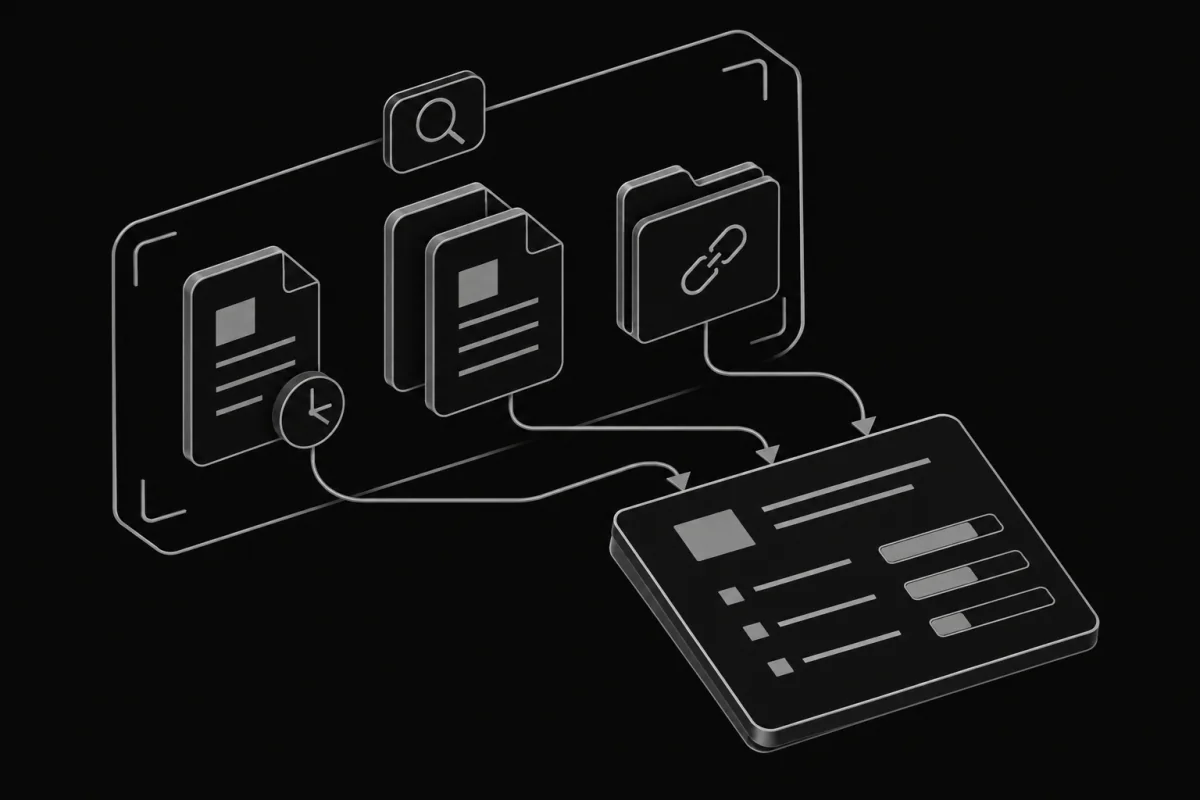
Data nobody has opened in years. Duplicate copies. Orphaned files and folders whose owners left long ago. All of it quantified in terabytes and cost, in one savings report.
Why it's safe to act on
Before it recommends anything, Smartstorify checks what still depends on the data, across every layer of your data center and cloud. Then your team decides: data owners, IT and compliance approve or reject each recommendation, and nothing changes until they do. Approved actions export as CSV or JSON for your own scripts.
- Data dependencies
- Your team approves
- CSV / JSON export
Keeps it clean, year after year
Storage waste comes back. Smartstorify keeps watching: new stale, duplicate and orphaned data is flagged as it appears, and the savings report stays current. The savings hold every year, not just after a one-time cleanup.
- New waste
- Human review
- Savings report
What makes it unique
Trained on synthetic data
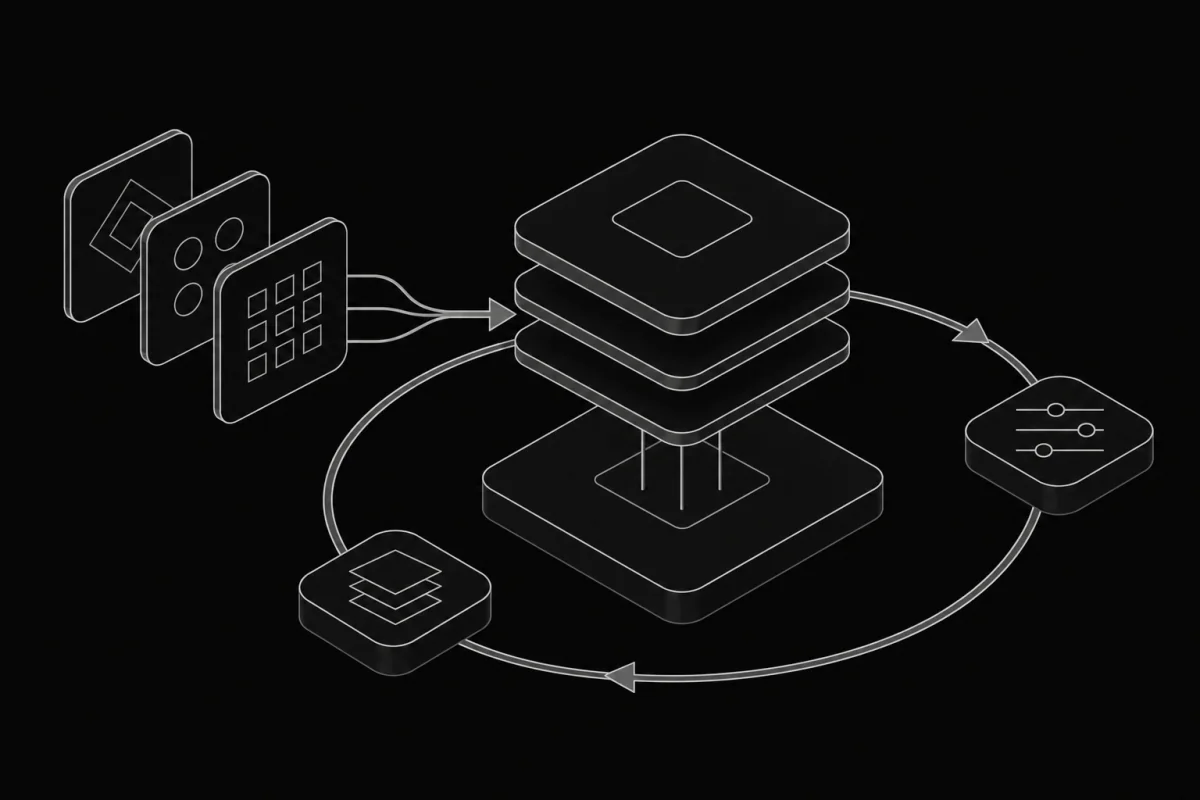
We train the core model on synthetic data in the Smartstorify lab, then deliver it to your organization. It is never trained on other customers' data, or on yours: once installed, it learns your environment locally, and that learning stays with you.
Sees your whole IT stack
Smartstorify looks at your data across every layer of your data center and cloud, including compute and networking, not at storage in isolation. It sees which data is used, which isn't, and what still depends on it, then recommends what to archive, move or remove.
Learns your environment
Once installed, the model learns your environment locally. Every recommendation goes through your review process: data owners, IT and compliance teams review it and approve or reject it before anything changes. The product is designed to remember those decisions in a knowledge base inside the product (a RAG stack) and use them to inform the next recommendation. The longer it runs, the better it knows your infrastructure, and that knowledge becomes part of your organization's institutional memory. It stays with you.
Your data never leaves your perimeter
The central engine and its lightweight agents run inside your perimeter, on-premises or in your own cloud. Lightweight agents connect to storage, servers and network switches in both your data center and your own cloud. The central engine can run in either environment. Your data never leaves your environment, and your security team can inspect and test the whole product, engine and agents included, however it needs to.
- Open to Security Review
- In-Perimeter Analysis
- Lightweight Agents
- Edge Deployment
No GPU farm required
Smartstorify runs on lightweight GPU or standard CPU. There's no dedicated AI infrastructure to buy or manage.
Roadmap
One AI-native engine, not four bolted-together tools. Clean is live now. Optimize, Govern and Operate follow through March 2027.
- Live
Clean(Storage Waste Remover)
Finds stale, duplicate and orphaned data and recommends what to remove
- Dec 2026
Optimize
Recommends where data should live: tiering, migration and capacity planning
- Mar 2027
Govern
Finds sensitive and regulated data, maps it against your policies and flags risks before anyone acts on it
- Mar 2027
Operate
A copilot across Clean, Optimize and Govern that gives policy-guided recommendations across the full data lifecycle, so your team knows what to do next
Built with Ollama, Python, TensorFlow, NoSQL, REST API